 Primary Source: Ollama Docs
Ollama GPU Offload & Context Length Tuning: Fixing CPU Fallback, OOM & Slow Token Generation
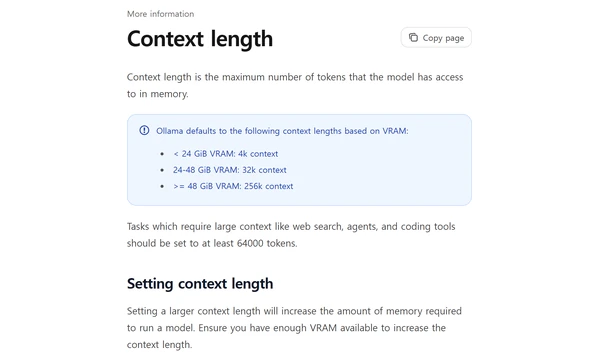
How to diagnose partial CPU/GPU memory splits with ollama ps, override Ollama's VRAM-based default context lengths (4k/32k/256k), and configure OLLAMA_CONTEXT_LENGTH, num_ctx, and CUDA_VISIBLE_DEVICES.