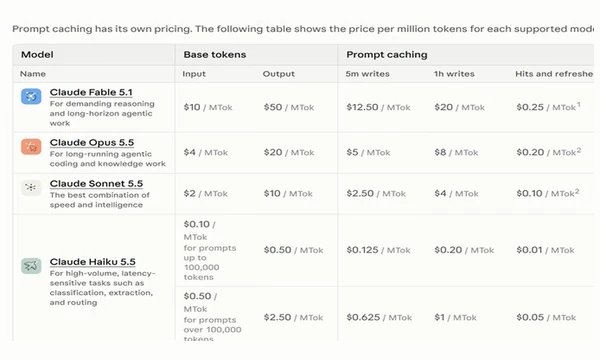
Compare three illustrative architectures at 1,000 queries using explicit token counts, a stated reranker allowance and a cache warm-up. This is a cost scenario, not a measured latency or quality benchmark.
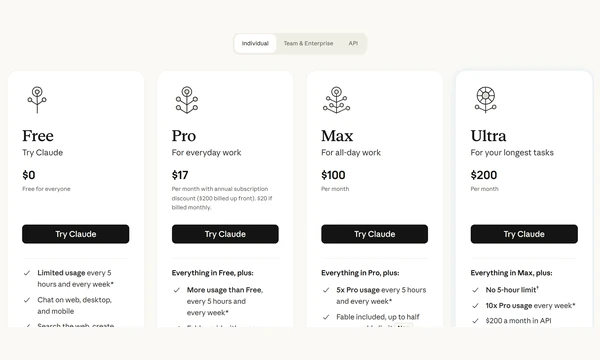
Compare current Claude subscription prices and included API credits with a clearly labelled enterprise spending example. A price crossing alone cannot prove that a subscription covers the same work.
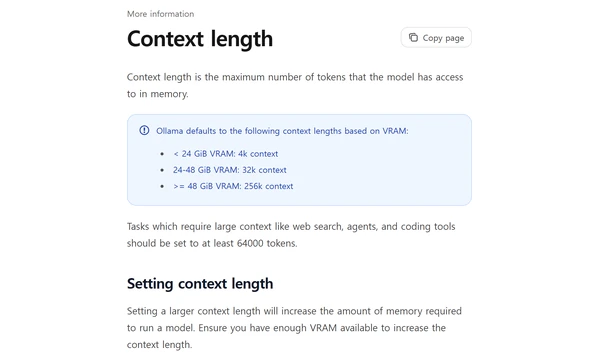
How to diagnose partial CPU/GPU memory splits with ollama ps, override Ollama's VRAM-based default context lengths (4k/32k/256k), and configure OLLAMA_CONTEXT_LENGTH, num_ctx, and CUDA_VISIBLE_DEVICES.
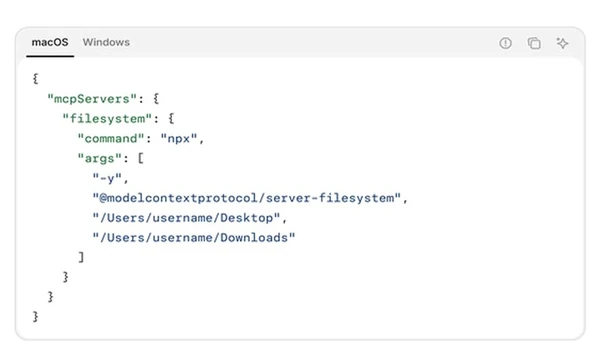
Why local Model Context Protocol (MCP) servers fail to launch with spawn npx ENOENT or Server disconnected in Claude Desktop, and how to fix claude_desktop_config.json on Windows (cmd /c wrapper), macOS, and Claude Code.
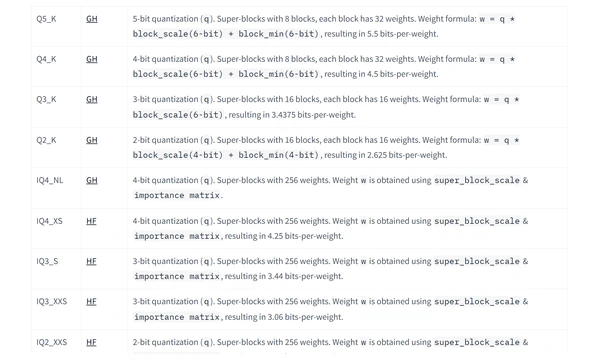
Estimate GGUF weight memory and architecture-based FP16 KV cache for four reference models. Use GiB consistently, include runtime allowance, and compare a capacity budget with actual available VRAM.
A side-by-side breakdown of per-million token rates, 5-minute and 1-hour prompt caching multipliers, 50% asynchronous batch discounts, and tokenizer overhead across Claude Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 5.5, and Google Gemini 4 Argon / 3.8 Flash.
 Primary Source: AWS Bedrock · Anthropic