Inside On Lab.
AI STACK · COST & BENCHMARK LABSearch Guides
Interactive Tool #2 · GPU VRAM

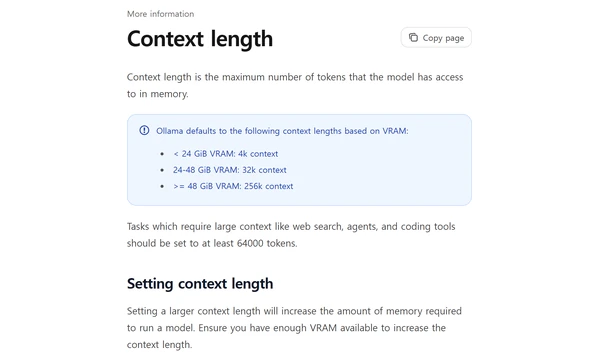
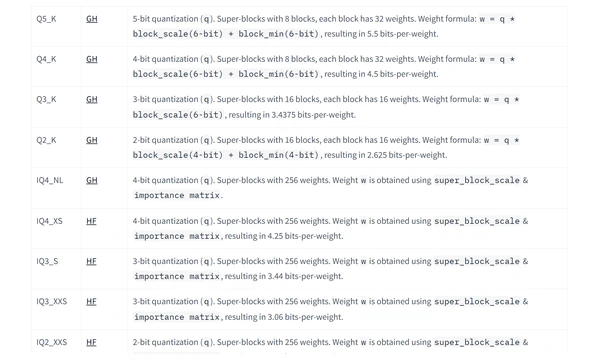
Local LLM GPU VRAM Calculator: GGUF Quantization & FP16 KV Cache Estimator

Calculate static GGUF weight memory (Q4_K_M, Q5_K_M, Q8_0, FP16), architecture-based FP16 KV cache across 4K–128K context windows, and GPU capacity targets for 8B–70B models.

Verified against Nov 2026 Vendor Docs← Back to Interactive Tools Board (3)
INTERACTIVE TOOL #2 // CLIENT-SIDE CALCULATOR

Local GGUF Model Weights & FP16 KV Cache VRAM Estimator

Static Model Weights~17.9 GiBQuantized GGUF tensor footprint
KV Cache + CUDA Buffer9.0 GiBArchitecture-based FP16 KV + runtime allowance
Estimated Total Memory~26.9 GiBBefore the capacity reserve
Capacity Target32 GiB+ usable VRAMIncludes 10% reserve; runtime fit not guaranteed
Adjust model parameters, quantization, and context window to calculate GPU VRAM requirements.
Quick Reference: Reference GGUF Architectures & 8K Context Memory Budgets (Q4_K_M + FP16 KV Cache)
Reference ModelLayers / KV HeadsQ4_K_M WeightsFP16 KV (8K / 32K)8K Total (+1 GiB Buf)Capacity Target (+10%)
Llama 3.1 8B32 layers · 8 KV heads~4.47 GiB1.00 GiB / 4.00 GiB~6.47 GiB8 GiB+ usable VRAM
Qwen2.5 14B48 layers · 8 KV heads~7.82 GiB1.50 GiB / 6.00 GiB~10.32 GiB12 GiB+ usable VRAM
DeepSeek R1 Distill Qwen 32B64 layers · 8 KV heads~17.88 GiB2.00 GiB / 8.00 GiB~20.88 GiB24 GiB+ usable VRAM
Llama 3.3 70B80 layers · 8 KV heads~39.12 GiB2.50 GiB / 10.00 GiB~42.62 GiB48 GiB+ usable VRAM
Verification & Billing Methodology Notice

Rate tables are a November 9, 2026 documentation snapshot with announced schedule changes shown where available. Calculators use stated assumptions and are estimates, not invoices or measured hardware benchmarks. Check actual usage categories, account terms, cache behaviour, runtime allocations and cloud endpoint rates for a production decision.
Related Engineering Guides & Primary-Source Deep Dives

All Guides